The Small-Win Sequencing Logic That Makes Industrial AI Stick Before Anyone Asks About Scale
Start with one painful process and let each win feed the next.
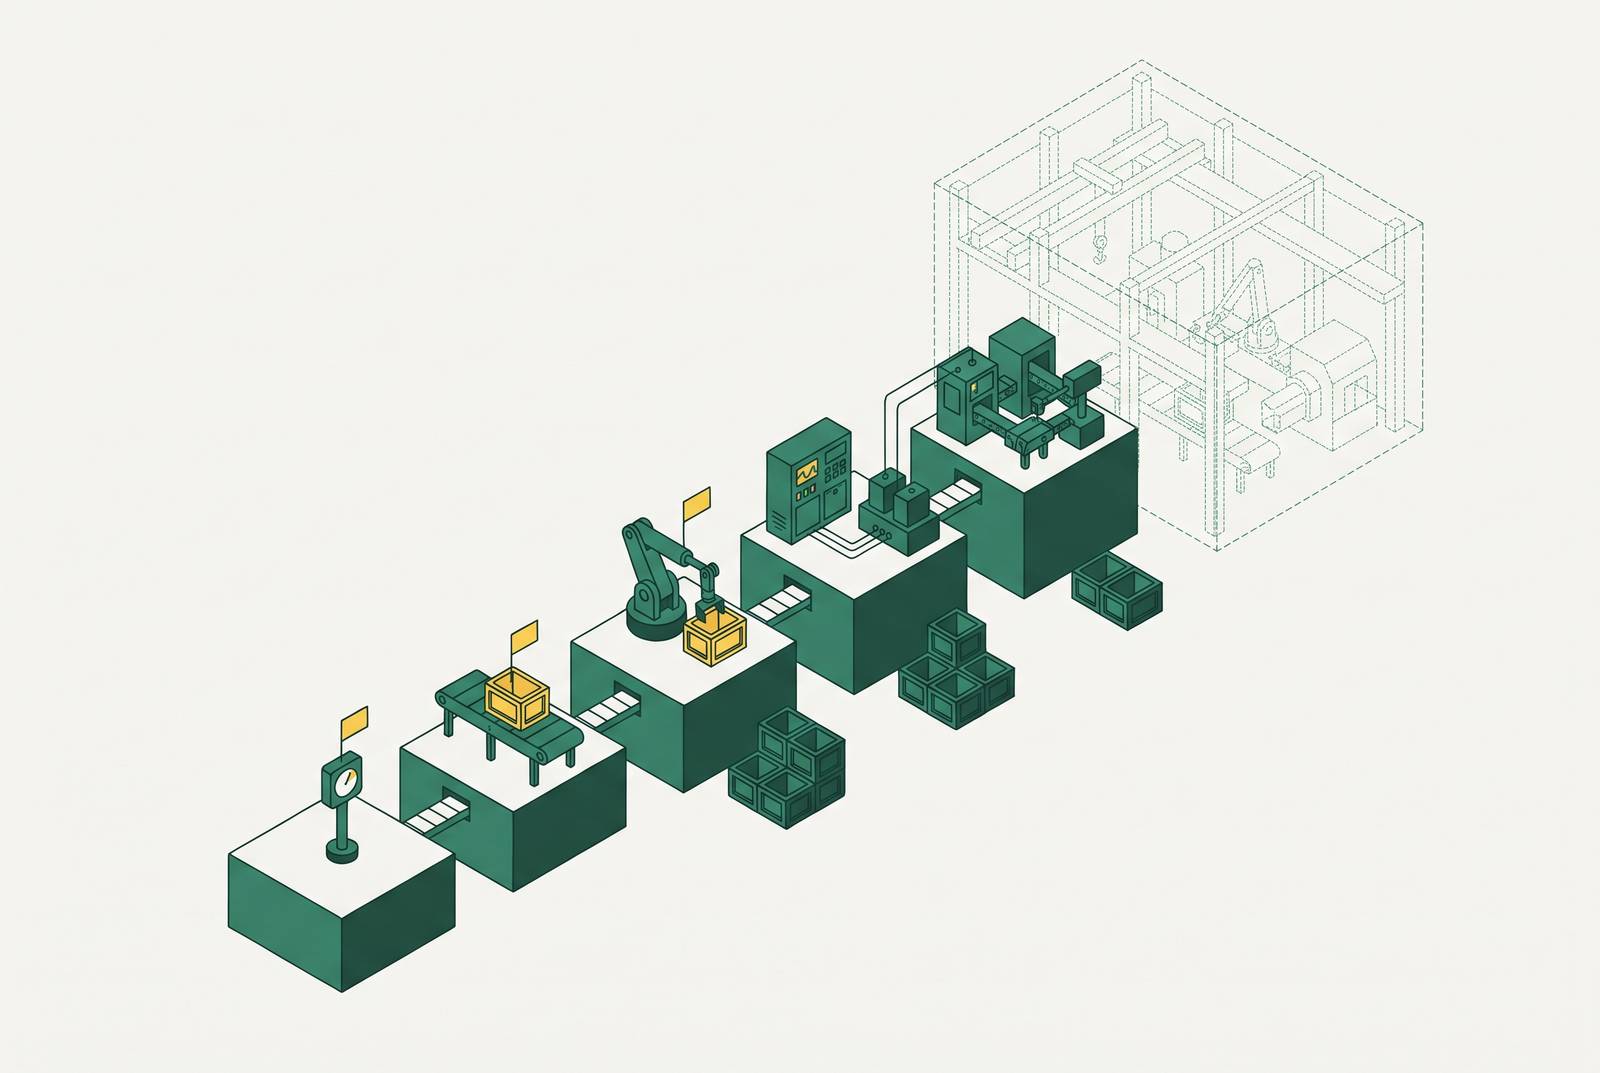
Industrial AI operational improvement can start without a platform strategy or a digital roadmap. Redesigning one painful process allows a scoped deployment to produce the data quality, tested decision boundaries, and operator trust the next deployment needs. Small-win sequencing is how operations in asset-heavy industries acquire the foundations for transformation.
Why industrial AI deployments keep failing after promising pilots
An agent makes procurement recommendations from forecasts that have never been validated at the line level. A scheduling tool finds an efficient path through activities even though their dependencies are wrong. Both systems can seem to work well yet do little to help the operation over time. The workflow remains broken beneath the new software. When AI accelerates its execution, the unresolved disorder spreads faster.
This is the central failure pattern behind promising pilots that do not become dependable operations. The generative AI wave led many to try it, but those trials did not always yield returns they could measure. Technical performance alone cannot close that gap because the deployment inherits the assumptions, handoffs, and records of the process it enters.
What would this workflow look like if it were being designed for an AI agent from scratch? That question often produces a different allocation of decisions and human review from the existing workflow. The redesigned process gives the agent a workable operating environment. Bolting it onto the old one avoids precisely the work that makes deployment useful.
What sequencing actually is — and what it is not
Small-win sequencing is a progression in which each deployment produces inputs required by the next. Those inputs include better-labeled data, demonstrated decision boundaries, operator familiarity with recommendations, and evidence that can justify expanded autonomy. The stages are not merely smaller versions of the same rollout. They establish different operating conditions.
That distinction separates sequencing from caution for its own sake. Teams that treat every pilot as protection against risk can keep testing forever, with no rules for when to move on. Treating a deployment as a producer of operational evidence creates an exit condition. The stage ends when it has produced the outputs the next stage needs.
AI-as-assistant, AI-as-agent, and autonomous operations are distinct operating models. Moving between them requires evidence about what the system can decide and what still needs human judgment. Sequencing therefore does not require a platform strategy, a broad transformation roadmap, or a multi-year change management program at the outset. It begins with one specific, painful process.
How skipping stages collapses the foundation rather than compressing the timeline
Slow sequencing can let competitors pull ahead if they are willing to bear the costs of early failures at scale. A business that takes care in deployment still has to keep up with competitors. And a small pilot does not always move the business forward.
However, accepting failure costs is different from having the foundations needed to learn from failure. Autonomous reordering cannot establish dependable performance against inventory records that have never been cleaned. A scheduling engine cannot correct its deployment's premise when the schedule does not describe reality. As the scope grows, those defects affect more decisions. It does not validate the inputs.
In logistics, supervised routing and targeted inventory recommendations produced useful operational gains, while fully autonomous forecasting underperformed and human judgment remained essential. That contrast undercuts the assumption that removing intermediate stages necessarily advances operational capability, without establishing a universal pace for adoption.
Timing adds another dimension to sequencing. Deployment during low-volume periods supports higher adoption and fewer operational disruptions, making the operating window part of the decision. The first deployment must also remain small enough to correct the data problems it exposes.
Manufacturing: where the sequencing logic shows up in the data problem first
Predictive maintenance exposes the data prerequisite with particular clarity. Sensors can transmit operational readings continuously, but supervised models also need records of when previous failures occurred and what type they were. Those histories may be inconsistent or kept on paper. The first task is often digitizing the failure log. Instrumentation alone does not supply the labels needed to interpret it.
The recommended starting scope is the twenty to thirty critical assets where downtime hurts most. That concentrates the work where failure is consequential while limiting the data that must be cleaned and labeled. Domtar's deployment at its Kingsport, Tennessee mill illustrates the constrained operating model. Waites AI-assisted vibration sensors monitor the equipment, and a Waites analyst and the mill reliability team review the alerts. Human review remains part of the deployment.
BMW Group and Figure AI also started by inserting sheet-metal parts into body-shop fixtures at Plant Spartanburg. The sequencing-trolley task came later, with Figure 03.
Implementation calls for partnering for strategy and design, buying proven commercial solutions for implementation, and building internal capability to operate and iterate. Formal feedback loops give operators and engineers a way to flag recommendations and help improve the model. Beyond its immediate result, the first deployment produces labeled failure data, familiarity with AI-flagged anomalies, validated sensor infrastructure, and a tested boundary between recommendations and decisions.
Construction: why sequence is determined by the data that precedes the schedule, not the schedule itself
A construction scheduling tool is downstream of the schedule it processes. If the baseline contains wrong logic ties, the engine can propose an optimal sequence of activities that cannot happen in that order. The tool may be working correctly. Its inputs are not a reliable account of the work.
The 2026 Roadmap on Artificial Intelligence and Machine Learning for Smart Manufacturing identifies data management and integration with heterogeneous systems as critical industrial AI challenges. Construction exposes the same structural dependency through schedules, procurement records, and coordination handoffs. Before a scheduling engine can improve execution, those inputs must describe the constraints execution will encounter.
Procurement connects the schedule to those constraints. AI procurement tools can forecast material needs, flag price volatility, recommend order timing, and identify mismatches between purchase orders, deliveries, and invoices. But schedule-based forecasts depend on realistic procurement lead times. An internally consistent schedule can still be unusable if its assumptions about material availability are wrong.
Energization readiness has the same problem. Many mission-critical projects are ready for construction before the power infrastructure is in place, reversing the long-held assumption that power will be there when needed. Optimizing construction activities does not remove that prerequisite. Work therefore begins at the painful intersection where schedule assumptions, procurement lead times, and coordination handoffs conflict most visibly. Auditing those records before deployment prevents a known data problem from becoming embedded in the AI system.
Logistics: how deployment order determines whether ROI compounds or stalls
In logistics, gains in one operating layer can give the next layer usable inputs when deployments proceed in the right order. Transport decisions, warehouse activity, and wider orchestration depend on related signals, but their readiness is not interchangeable. A useful recommendation at one layer does not justify autonomy across all three. Progress depends on what the preceding deployment has established.
AI-assisted routing during disruptions demonstrated a constrained entry point in 2025. Routing engines produced alternative scenarios faster than planners could assess them by hand, but humans still made the final decisions. The immediate benefit was reduced comparison time. The operational value also included familiarity with recommendations in a defined decision setting.
At the inventory layer, multi-agent pilots recommended specific moves between distribution centers. They monitored forecast deltas, inbound variability, capacity constraints, safety stock thresholds, and fulfillment cycle times. Small gains over time helped validate the data model without the need for high autonomy. That validation provides a stronger basis for wider orchestration than an untested assumption that the signals are dependable.
Fully autonomous forecasting, by contrast, underperformed in 2025 because human judgment remained essential. The architectural distinction follows from that evidence. Bolt-on AI leaves the existing decision process largely unexamined, while embedded AI has a defined place in the workflow, including its human review boundary. Sequencing establishes that place before extending it.
Retail: what field evidence reveals that declared plans conceal
Deloitte's 2026 survey of retail and consumer products executives found a gap between declared AI priority and operational execution, with broad adoption lagging outside IT. Strategic intent is not an operating condition. Workforce readiness deepens the gap when frontline staff have no available AI training or use AI daily without formal preparation. A deployment can be active without the informed operator feedback needed to validate and improve it.
NARG, a multi-billion-dollar specialty retail chain, illustrates a more explicit sequence. In Q3 2025, its SVP of Digital Transformation described the company as running a 2015 playbook against 2026 expectations. The transformation consolidated onto a single national communications company and rolled out managed SD-WAN to every store. It then deployed seven AI workloads into production. Attribution of a margin improvement followed those deployments.
The order is the significant feature of the case. NARG's infrastructure work does not mean that every first process needs a commitment to an enterprise platform. It shows that the prerequisite must match the problem.
Augmodo provides a product-level contrast to NARG's infrastructure-level sequence. Both cases identified a specific operational problem, validated a fix at contained scope, and then expanded on the evidence produced. Neither treated a declared ambition to transform everything as evidence of readiness to do so.
What each stage of the sequence actually produces for the stage that follows
The first output is data quality. Operational use exposes missing labels, sensor blind spots, and inconsistent records that may remain hidden during preparation. Resolving those gaps makes the next deployment's inputs more dependable. The roadmap identifies data management and integration with heterogeneous sensing and control systems as unresolved industrial challenges. A deployment with a limited scope tests those conditions before they affect more of the operation.
The second output is a documented decision boundary. A constrained deployment reveals where recommendations are reliable, where human review is necessary, and where the system fails. That boundary defines the available scope for expansion. Without it, a request for more autonomy rests on an unsupported claim about capability. The next stage needs the distinction made explicit.
The third output is organizational trust grounded in operator calibration. Operators who have evaluated correct recommendations and participated when recommendations were wrong have a basis for judging the system. They need to distinguish reliable advice from advice that requires intervention, because that judgment sustains the feedback loops through which the model improves.
The fourth output is an audit trail. A documented deployment gives finance, operations leadership, and regulators where applicable an evidence base for the next investment. Readiness to advance therefore depends on clean and labeled data, documented decision boundaries, calibrated operators, and attributable results. Elapsed calendar time cannot substitute for any of those outputs.
How to choose the first process to fix with AI without buying a whole platform
The right first process is consequential but bounded. It contains a painful operational breakdown that is understood well enough to redesign and important enough that fixing it establishes credibility. The safest demonstration may not meet that standard. A low-stakes sandbox can show how the technology works without giving the next deployment anything it can build on.
The selection mechanism is a process audit. Before choosing what to rebuild, the team should map how the process runs today and where it hurts, distinguishing flaws in its logic from flaws in execution. A promising candidate has a manual decision with significant lag, a recurring and diagnosable failure mode, an existing data source even if inconsistently captured, and a human expert able to judge recommendations. Together, those conditions make the first deployment capable of producing the next stage's inputs.
Some candidates require prerequisite work instead. Data too sparse to train on, decision boundaries too ambiguous to validate, or scope too broad to isolate failure disqualify a process as an immediate AI starting point. In those conditions, data infrastructure comes first. Choosing a smaller label for an unbounded problem does not make it a scoped deployment.
Time to production provides another diagnostic. A first AI-first process that takes quarters rather than weeks signals a problem with process selection or the deployment approach because it delays real operational feedback. The initial plan need not settle the eventual scale of the program. It must establish how the first live process will generate evidence for a second. Which painful process has usable data, a diagnosable failure, and an expert who can judge recommendations, and can reach production in weeks so that those judgments begin?